> For the complete documentation index, see [llms.txt](https://help.connected.illumina.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.connected.illumina.com/connected-analytics/tutorials/nextflow.md).

# Nextflow Pipeline

In this tutorial, we will show how to create and launch a pipeline using the Nextflow language in Platform Core.

This tutorial references the [Basic pipeline](https://www.nextflow.io/example1.html) example in the Nextflow documentation.

## Create the pipeline

The first step in creating a pipeline is to create a [Project](broken://spaces/7GiJwg33pKa8eXmwcle7/pages/KB7sn3f0XqVT7MXGyNyp). In the example below, the project is named *Getting Started*.

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-373bc59f4c6b5833bec399f86fc3efafe04e5af4%2Fimage%20(83).png?alt=media" alt=""><figcaption></figcaption></figure>

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-219d0ce0b7054f7231b6a8bdac5b45acc624f560%2Fimage%20(36).png?alt=media" alt=""><figcaption></figcaption></figure>

{% stepper %}
{% step %}

### Open your project

Pipelines exist within a [Project](https://help.ica.illumina.com/home/h-projects), so the first step is to determine which project you want to use as home of your pipeline. In the example below, our project is named *Getting Started*. You can **open** the **project** (**Projects > your\_project**) where you want to create your pipeline or create a new project at **Projects > + Create.**
{% endstep %}

{% step %}

### Navigate to the pipelines inventory

Navigate to the **Projects > your\_project > Flow > Pipelines** inventory
{% endstep %}

{% step %}

### Create a new JSON-based pipeline

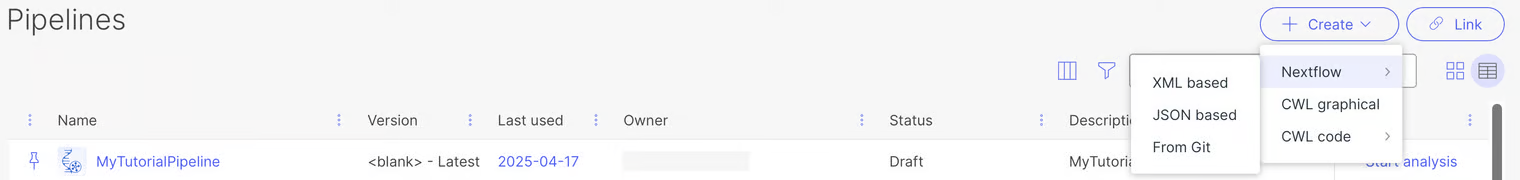
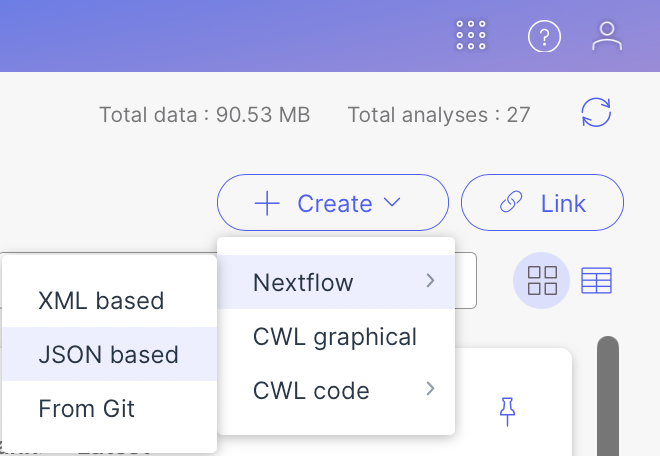
From the Pipelines view, click **+Create > Nextflow > JSON based** to start creating the Nextflow pipeline. This will open the pipeline details screen.

<div align="center"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-7585cf8c3a81c9c23c412d17136aa24d730d6f02%2Fimage%20(168).png?alt=media" alt="" width="165"><figcaption></figcaption></figure></div>
{% endstep %}

{% step %}

### Configure the general setting

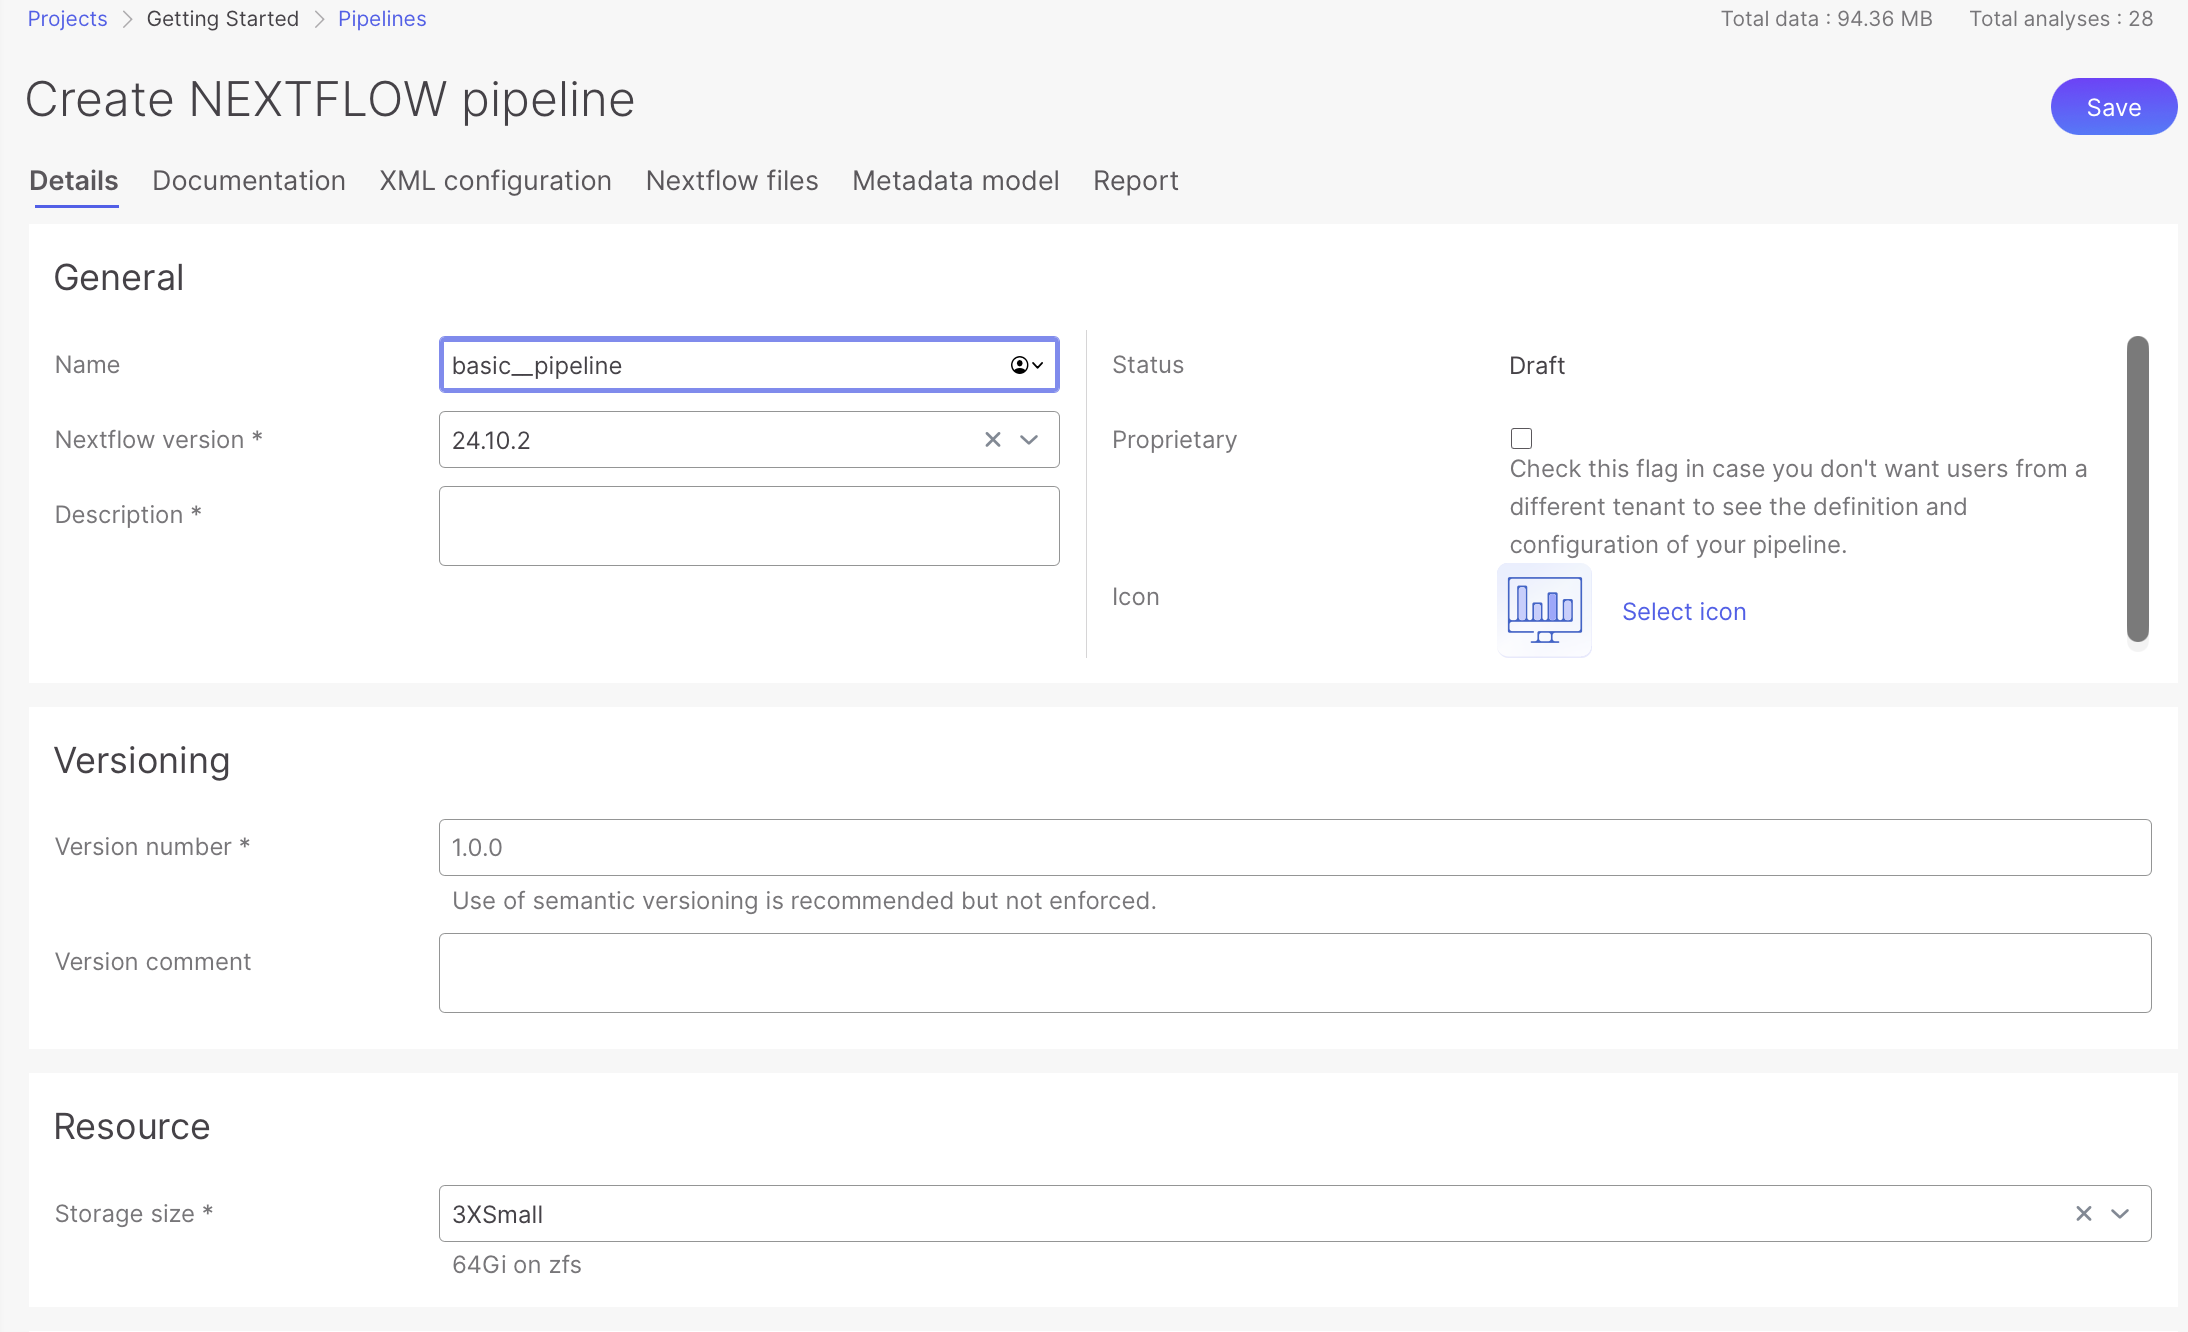
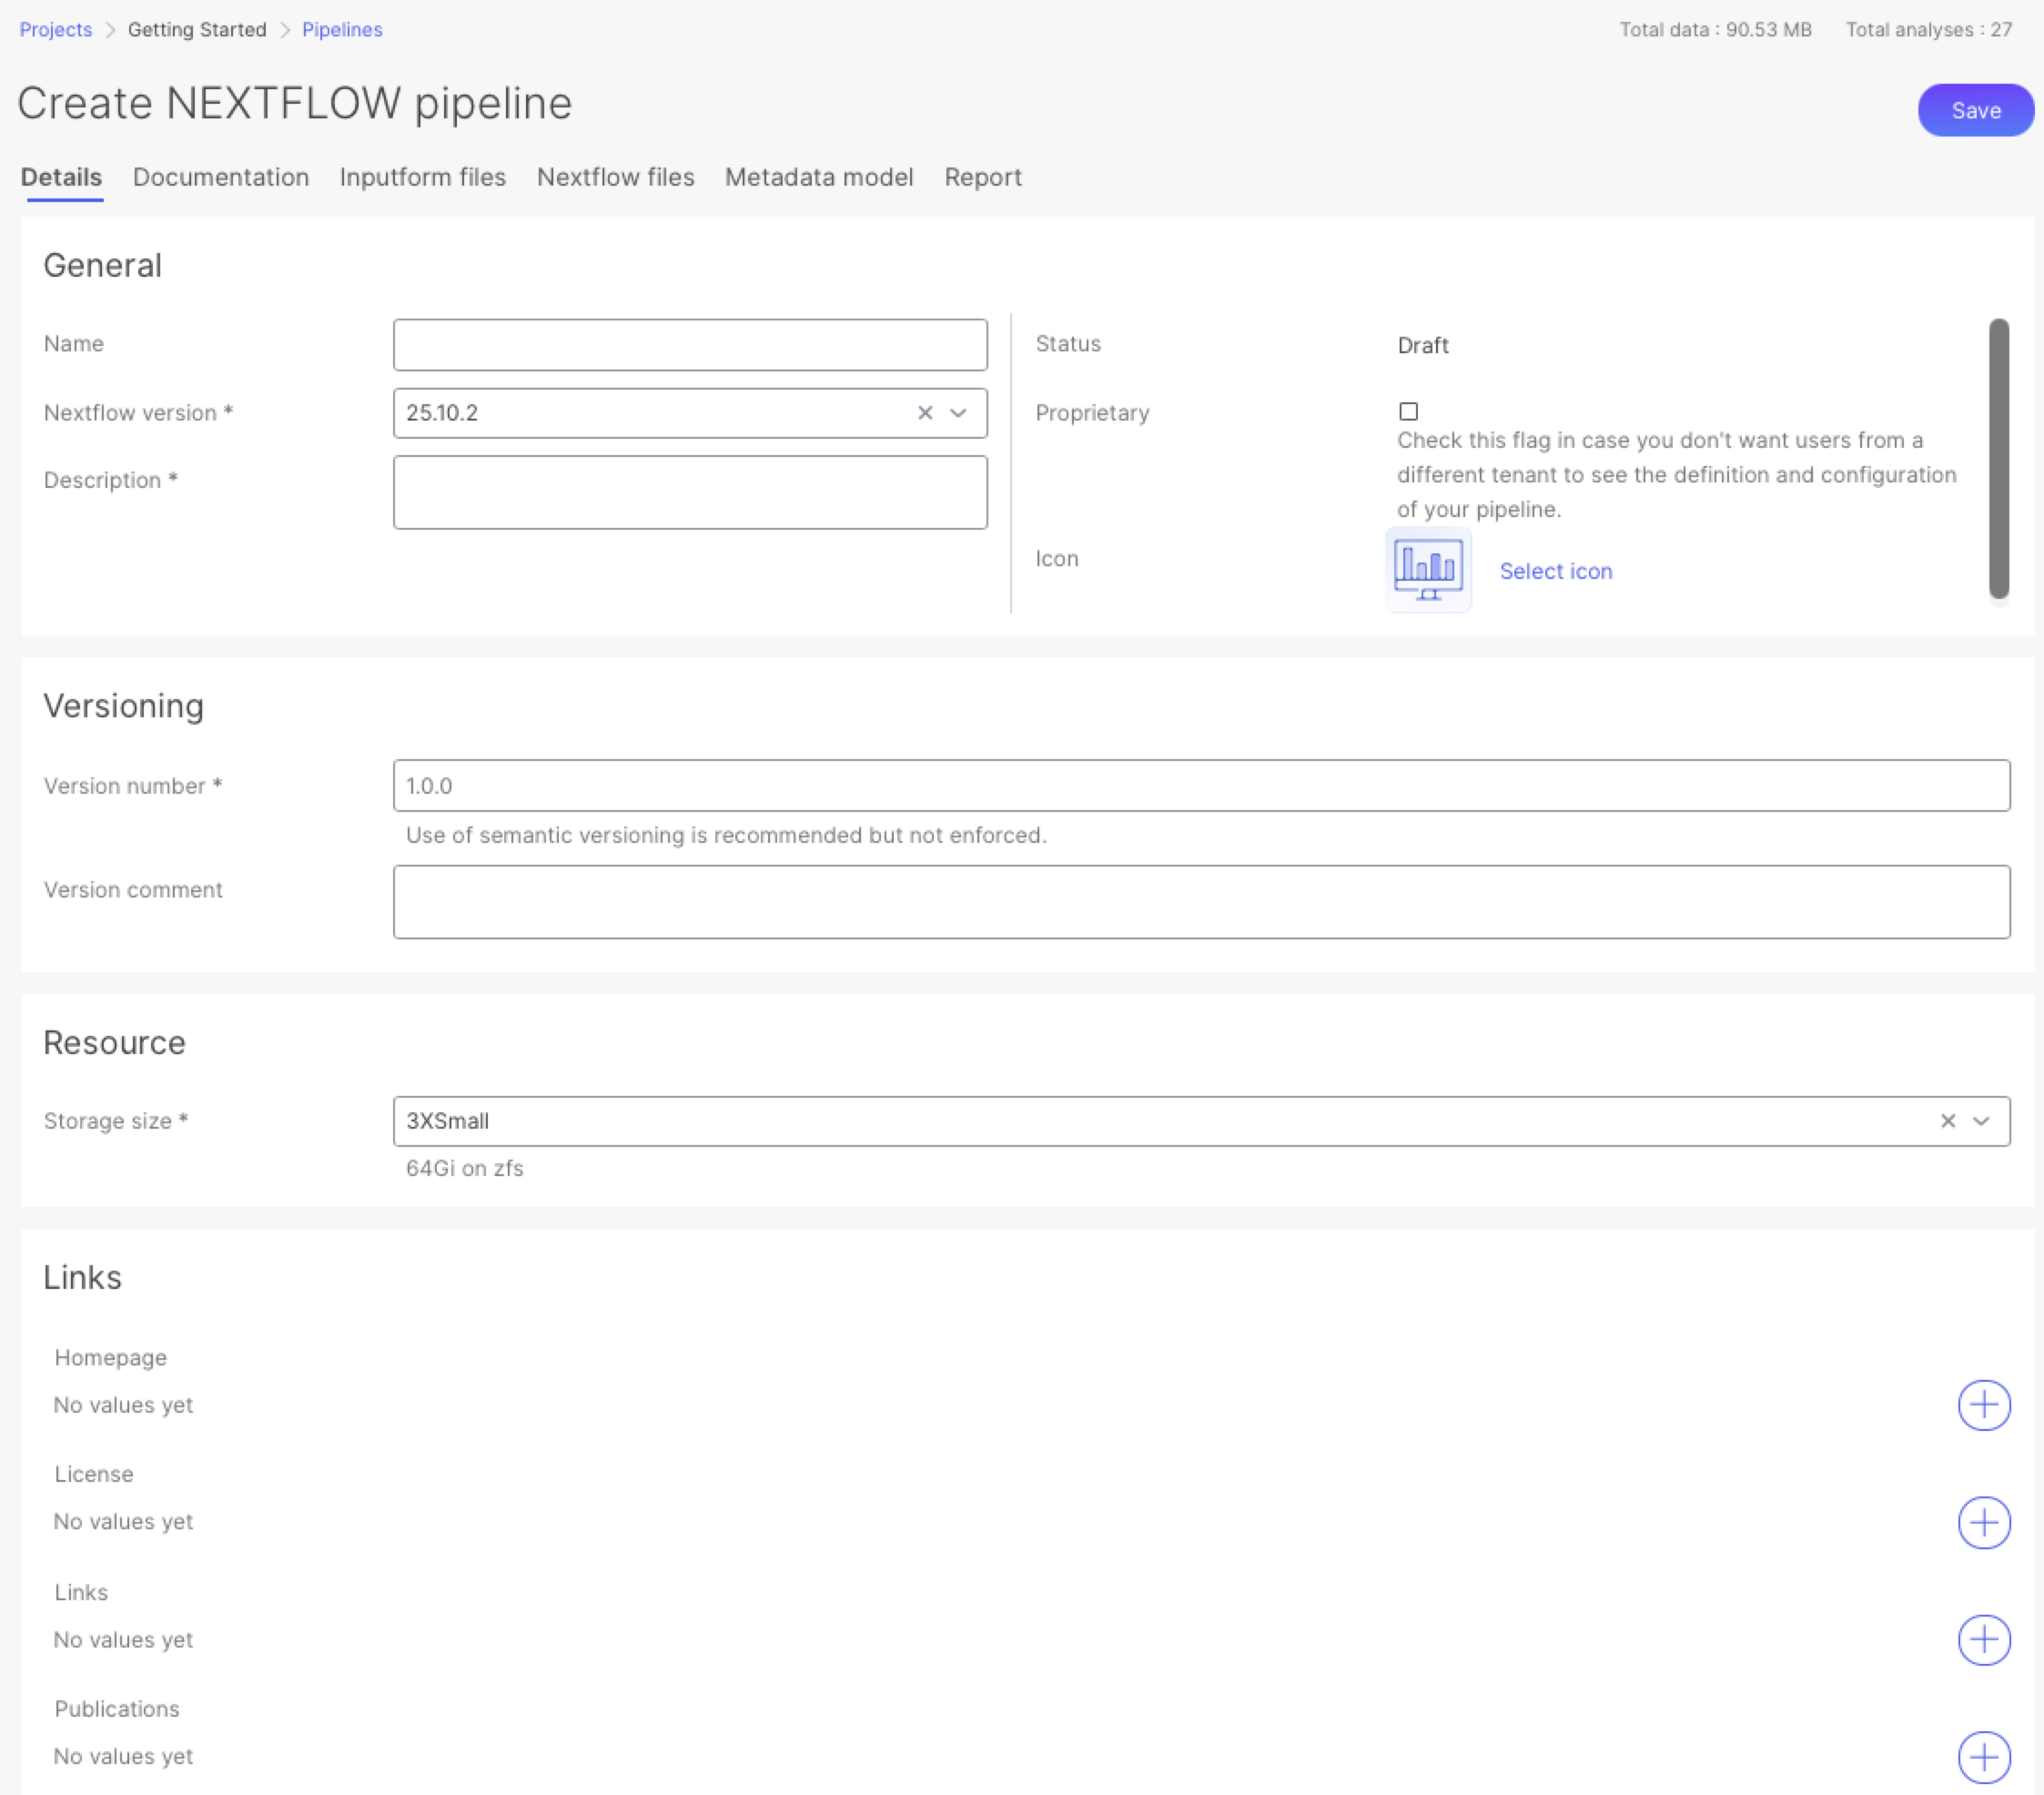
The [pipeline](broken://pages/YmL5q15lUdOBb8ZIwbAD) details screen is where you give your pipeline a **name**, **description** and **version** number and select your **nextflow version** and **storage size**.

<table><thead><tr><th width="190.35760498046875">Field</th><th>Entry</th></tr></thead><tbody><tr><td><strong>Name</strong></td><td>The name by which users can identify your pipeline. The name must be unique within your tenant to prevent users from selecting the wrong pipeline.</td></tr><tr><td><strong>Nextflow Version</strong></td><td>Select the nextflow version you want to use. For our example, this can be kept at the default version.</td></tr><tr><td><strong>Description</strong></td><td>A short description of the pipeline.</td></tr><tr><td>Status</td><td>The <a href="#pipeline-statuses">release status</a> of the pipeline. This is set to draft as we are editing this pipeline.</td></tr><tr><td>Proprietary (optional)</td><td>Restricts pipeline scripts and details to users in the owning tenant. Users outside the tenant also cannot clone the pipeline.</td></tr><tr><td>Icon</td><td>You can keep the default icon or select an alternative from the list of icons.</td></tr><tr><td><strong>Version Number</strong></td><td>Mandatory version number of your pipeline. Since this is the initial version, we can leave it at 1.0.0</td></tr><tr><td>Version Comment (optional)</td><td>You can provide additional information for this version of your pipeline here.</td></tr><tr><td><strong>Storage size</strong></td><td>Select a <a href="/connected-analytics/reference/r-pricing.md#data-storage">storage size</a> for running the pipeline. Since this is a very small basic pipeline, the smallest size you can select here will still be large enough.</td></tr><tr><td>Links (optional)</td><td>Here you can add links to external information by selecting the + icon.</td></tr></tbody></table>

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-9eec032875ab919d583ebd490677e2ef49682fb1%2Fimage%20(95).png?alt=media" alt=""><figcaption></figcaption></figure>

If you want to edit an existing pipeline later on, open it from **projects > your\_project > pipelines > your\_pipeline** by selecting the **three dots** at the top right and choosing **Edit**.
{% endstep %}

{% step %}

### Add the nextflow files

The actual work is done by the Nextflow pipeline, so we need a pipeline definition. The pipeline in this example is a modified version of the [Basic pipeline example](https://www.nextflow.io/example1.html) from the Nextflow documentation.

This simple end-to-end Nextflow workflow consists of two processes connected together. The first process **splits the FASTA file** into multiple files (one per sequence), the second process **reverses the contents** of each split file before they are merged again.

{% hint style="info" %}
Some modifications are made to the Nextflow pipeline, **you do not need to make these modification by hand. Copyable code is provided below.**

* Adding the `container` directive to each process with the desired ubuntu image. If no Docker image is specified, public.ecr.aws/lts/ubuntu:22.04\_stable is used as default. If you want to use the latest image, use *`container 'public.ecr.aws/lts/ubuntu:latest'`*
* Adding the `publishDir` directive with value `'out'` to the `reverse` process.
* Modifying the `reverse` process to write the output to a file `test.txt` instead of stdout.
* Creating a channel with the input file.
  {% endhint %}

Navigate to the **Nextflow files > main.nf** tab to add the definition to the pipeline. Since this is a single file pipeline, we don't need to add any additional definition files. Paste the following definition into the text editor:

```nf
#!/usr/bin/env nextflow
params.in = "$HOME/sample.fa"

// -----------------------------
// Processes
// -----------------------------

// Split the file
process splitSequences {
    container 'ubuntu:24.04'

    input:
    path input_fa

    output:
    path "seq_*"

    script:
    """
    awk '/^>/{outfile="seq_" ++d} {print >> outfile}' ${input_fa}
    """
}

// Reverse the Sequence
process reverse {
    container 'ubuntu:24.04'
    publishDir 'out'

    input:
    path x

    output:
    path "test.txt"

    script:
    """
    cat ${x} | rev > test.txt
    """
}

// -----------------------------
// Workflow block
// -----------------------------

workflow {
//     Create a channel with your input file
    sequences = Channel.fromPath(params.in)
    splitSequences(sequences) | reverse | view
}
```

{% hint style="info" icon="bug" %}
If you encounter the error "unexpected unbound variable", verify if you have set the container to the ubuntu version specified in the example above. This error is caused by an incompatibility between Nextflow and the uutils coreutils implementation in Ubuntu 26.04.
{% endhint %}

#### **Setting Process Resources (optional)**

For each process, you can use the [memory directive](https://www.nextflow.io/docs/latest/process.html#memory) and [cpus directive](https://www.nextflow.io/docs/latest/process.html#cpus) to set the [Compute Types](broken://pages/YmL5q15lUdOBb8ZIwbAD#compute-resources). Platform Core will then determine the best matching compute type based on those settings. Suppose you set `memory '10 GB'` and `cpus 6`, then Platform Core will determine you need the `standard-large` compute type.

Syntax example:

```nf
process iwantstandardsmallresources {
    cpus 6
    memory '10 GB'
    ...
```

{% endstep %}

{% step %}

### Create the input form

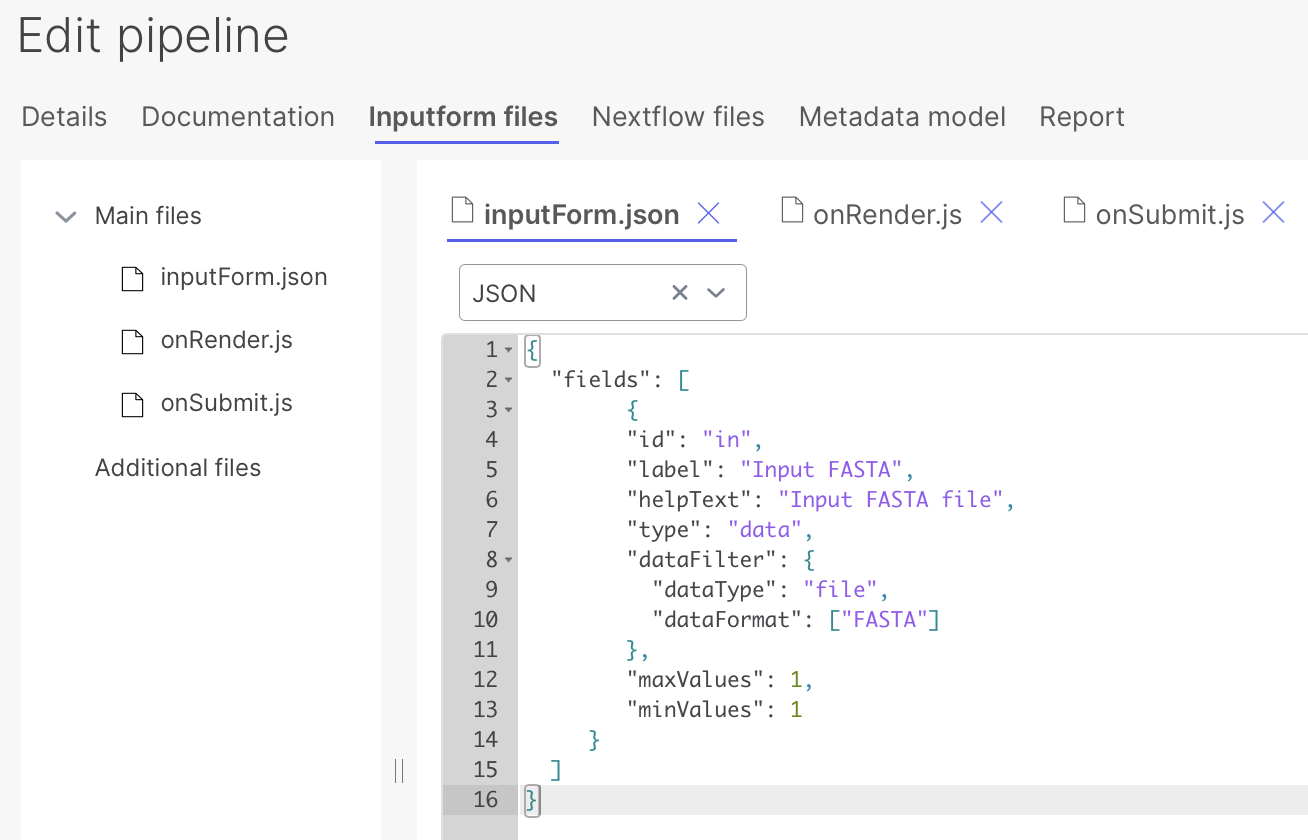
In order to run the pipeline, we need to be able to select the input file. The input form which we will create in this step is displayed when launching the pipeline and lets you select the input file. This is a JSON-based example, so the input form is created in the **Inputform files** tab.

The pipeline takes a single FASTA file as input, so we create a form which takes a single FASTA file as by having `dataType` set to file and `dataFormat` as FASTA. When both `minValues` and `maxValues` are set to 1, then a single file is mandatory input.

Paste the below JSON input form in the inputForm.json text editor.

```json
{
  "fields": [
        {
        "id": "in",
        "label": "Input FASTA",
        "helpText": "Input FASTA file",
        "type": "data",
        "dataFilter": {
          "dataType": "file",
          "dataFormat": ["FASTA"]
        },
        "maxValues": 1,
        "minValues": 1
     }
  ]
}
```

After pasting the content, your inputForm.json will look similar to this:

<div align="left"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-02bb67eb6ddea760629a77fc2c628f72b1279324%2Fimage%20(108).png?alt=media" alt="" width="563"><figcaption></figcaption></figure></div>

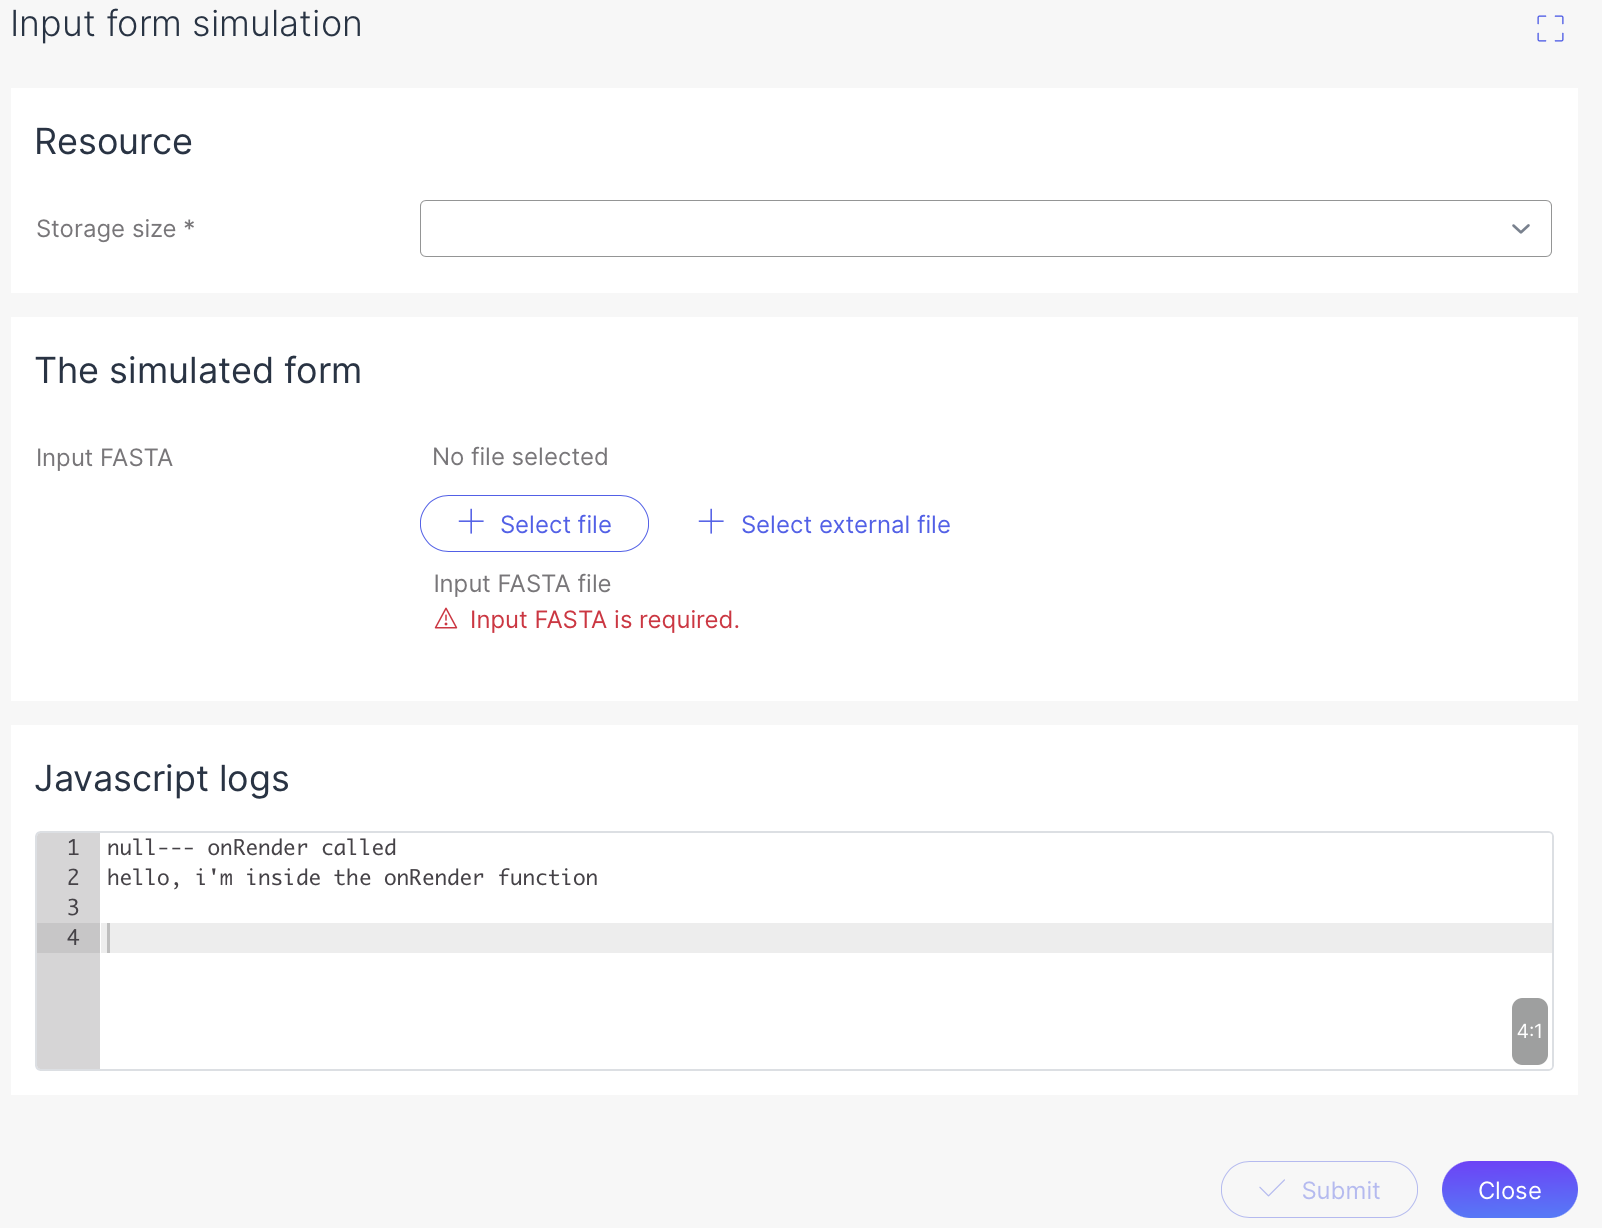
If you want to see what your actual input form will look like, use the **simulate** button at the bottom of the screen. This will show the resulting simulated form.

<div align="left"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-df5b95c2ee8c93b3a99cf00c7577233c4d0c4a0d%2Fimage%20(132).png?alt=media" alt="" width="375"><figcaption></figcaption></figure></div>
{% endstep %}

{% step %}

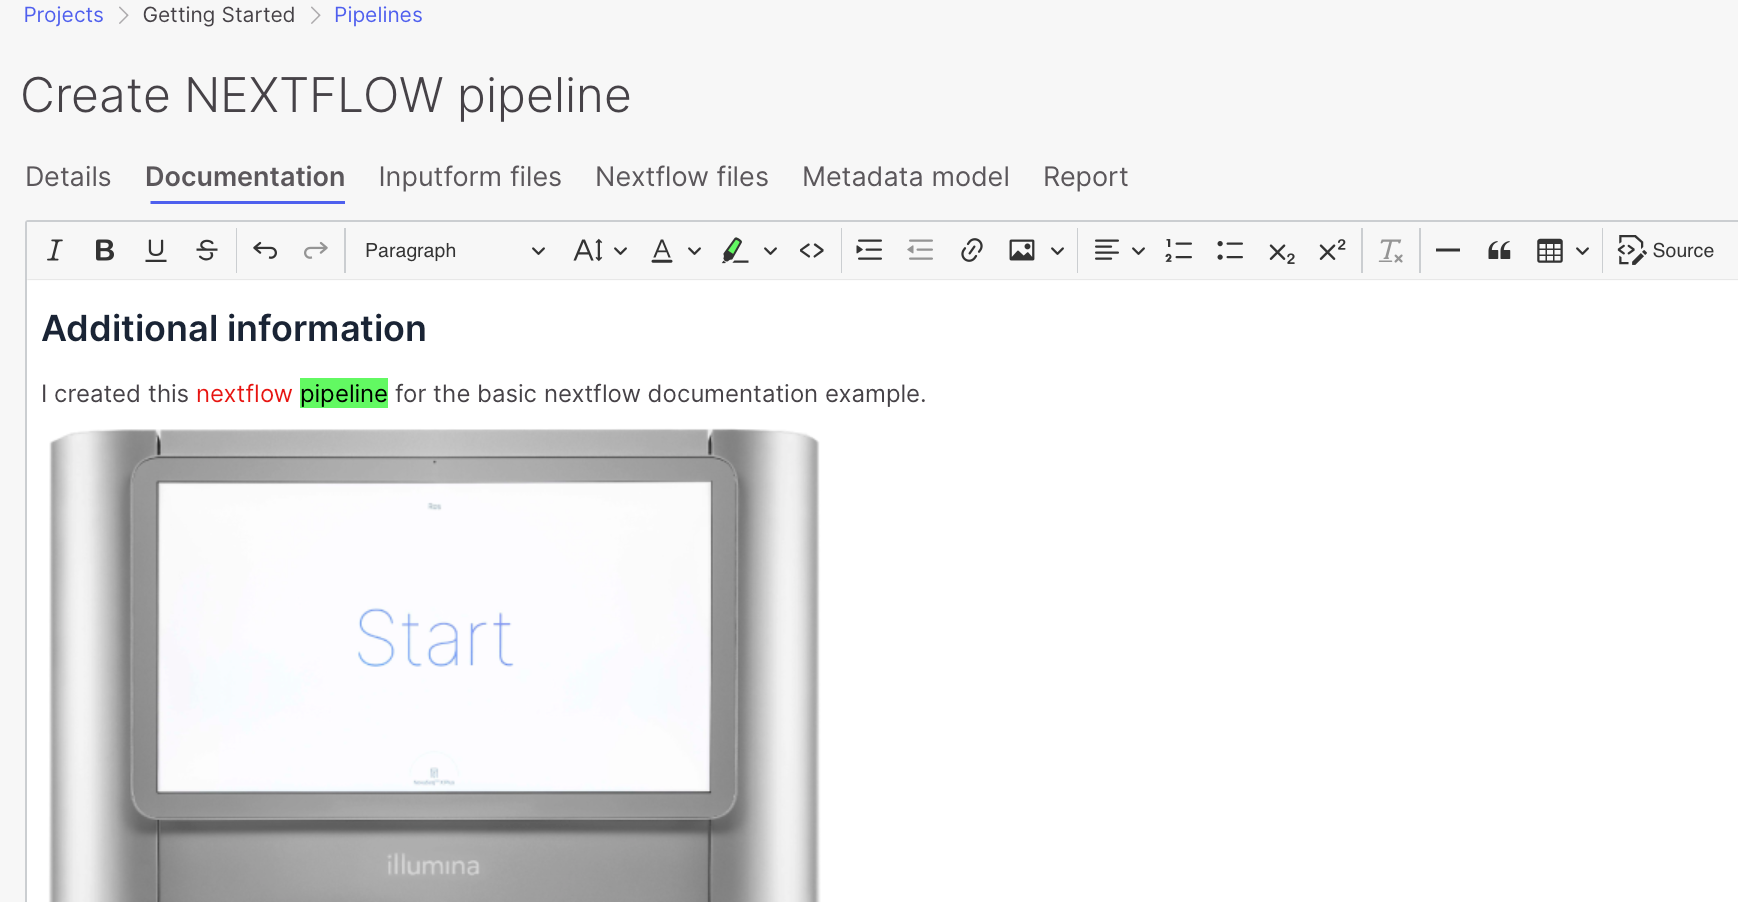
### Adding additional information (optional)

You can add information to your pipeline on the **Documentation tab.** Here you can add text, images and formatting to explain the details or purpose of your pipeline.

Your pipeline users can see this documentation by selecting the **view documentation** button when starting an analysis.

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-188c599d2ed8b6a53318df0dd98af6d3dca23fea%2Fimage%20(167).png?alt=media" alt=""><figcaption></figcaption></figure>
{% endstep %}

{% step %}

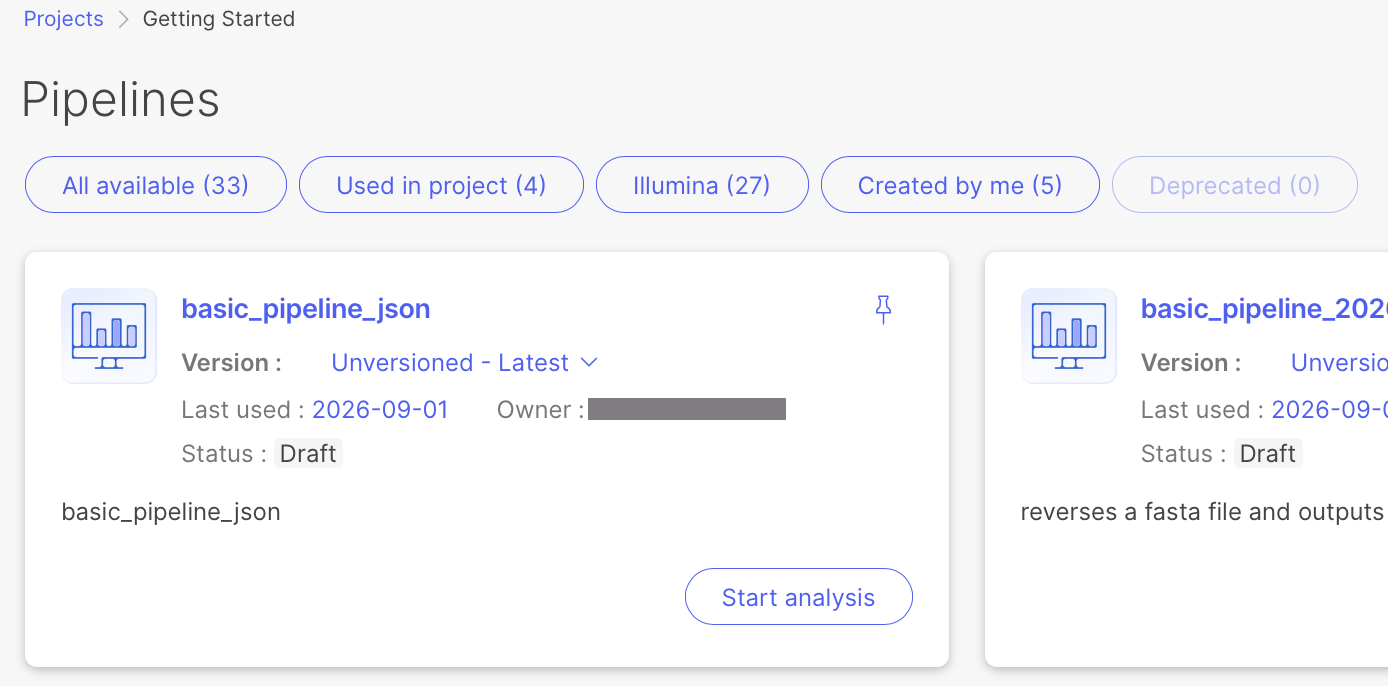
### Save the pipeline

Once the definition has been added and the input form has been defined, the pipeline is complete. Click the **Save** button at the top right.

The pipeline will now be visible from the **Projects > your\_project > Pipelines** view within the project.

<div align="left"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-53f97d48391243b304e7463d009b426d1219aca3%2Fimage%20(163).png?alt=media" alt="" width="563"><figcaption></figcaption></figure></div>
{% endstep %}
{% endstepper %}

## Launching the analysis

{% stepper %}
{% step %}

### Obtain the input file

Before launching the analysis, you need a FASTA file to use as input. For this tutorial, use a public FASTA file from the [UCSC Genome Browser](https://genome.ucsc.edu/). Download [chr1\_GL383518v1\_alt.fa.gz](https://hgdownload.cse.ucsc.edu/goldenpath/hg38/chromosomes/chr1_GL383518v1_alt.fa.gz) and unzip the file to obtain the decompressed FASTA file.
{% endstep %}

{% step %}

### Upload the file to Project Core

To upload the FASTA file to the project, navigate to **Projects > your\_project > Data**. (1) In the Data view, drag and drop the FASTA file from your local machine in the input section (2) in the browser. Once file upload completes, the file will show up in the Data explorer (3).

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-062889086df625e975cec0803754022aefde3f68%2Fimage%20(147).png?alt=media" alt=""><figcaption></figcaption></figure>

The file format will be auto-detected to be a FASTA file. If auto-detection fails, you can set the file type yourself by selecting the file and selecting **Manage > change format > FASTA**.
{% endstep %}

{% step %}

### Start the pipeline

Now that the input data is uploaded, we can proceed to launch the pipeline. Navigate to **Projects > your\_project > Flow > Analyses** click on **Start**. Select your pipeline from the list and choose **Select**.

{% hint style="info" %}
Alternatively you can start your pipeline from **Projects > your\_project > Flow > Pipelines > your\_pipeline > Start analysis**.
{% endhint %}

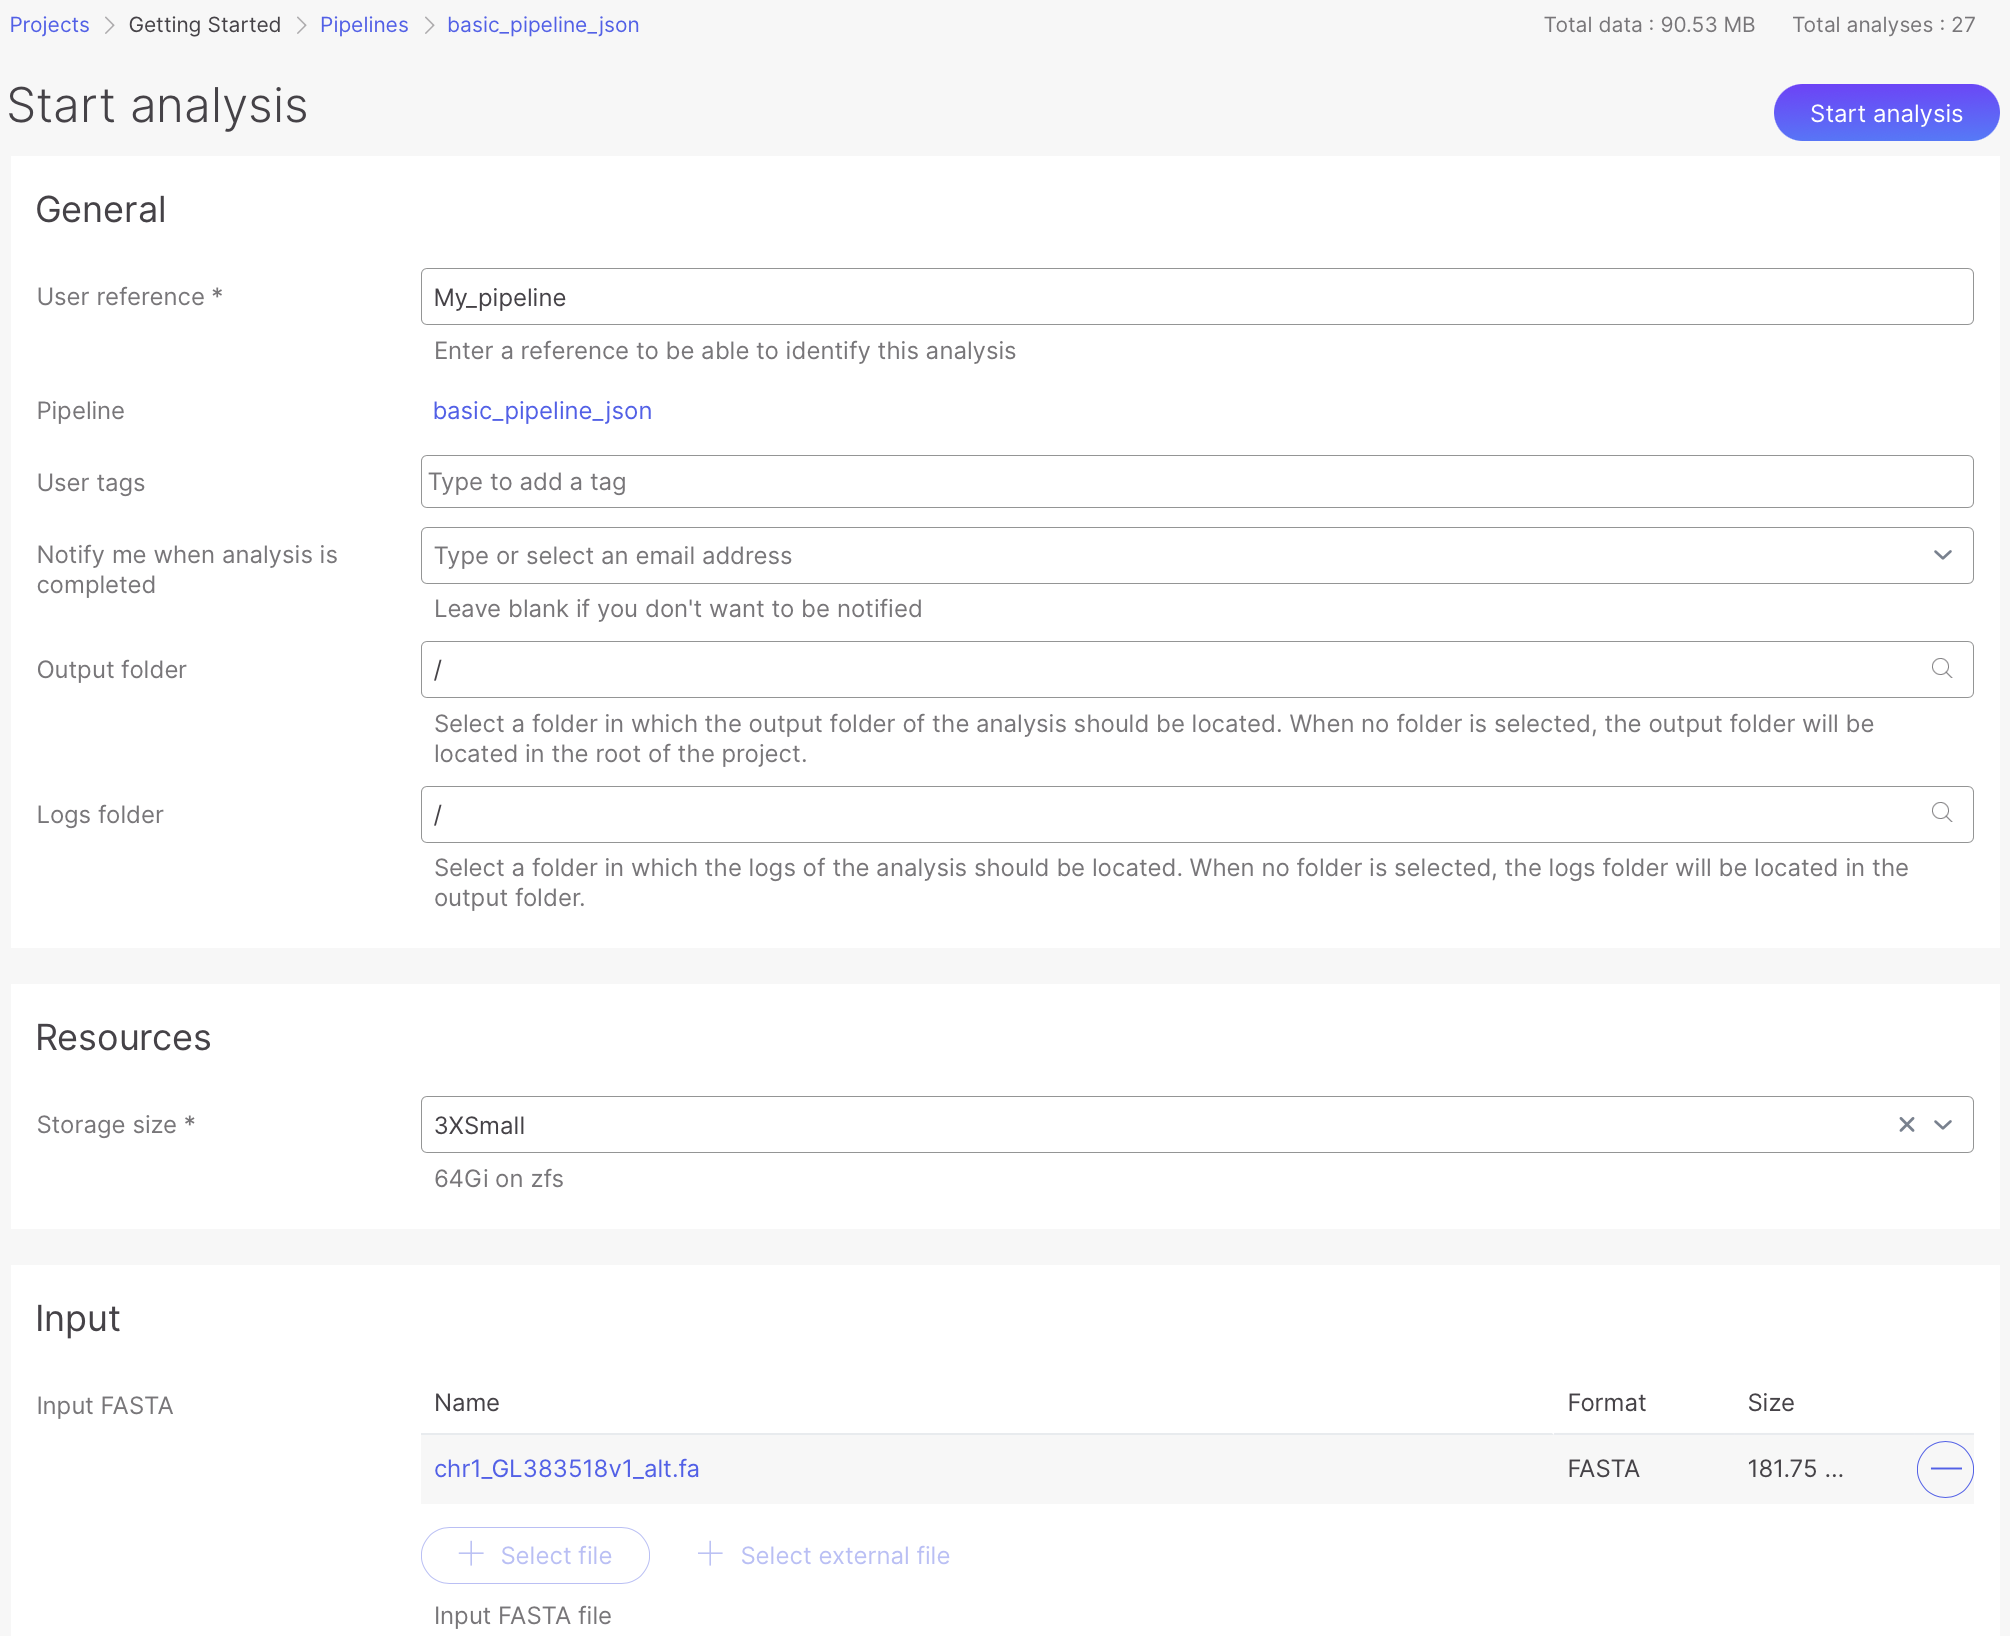
The pipeline input form will be displayed. Give your analysis a **name** in the user reference field, select a **storage size** and choose the previously uploaded input **FASTA file**.

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-896f191c41bd0e1ceb02414c43c456ed5dad29b5%2Fimage%20(164).png?alt=media" alt=""><figcaption></figcaption></figure>

With the required information set, click **Start Analysis**.
{% endstep %}
{% endstepper %}

## Monitoring the Analysis

{% stepper %}
{% step %}

### Progress

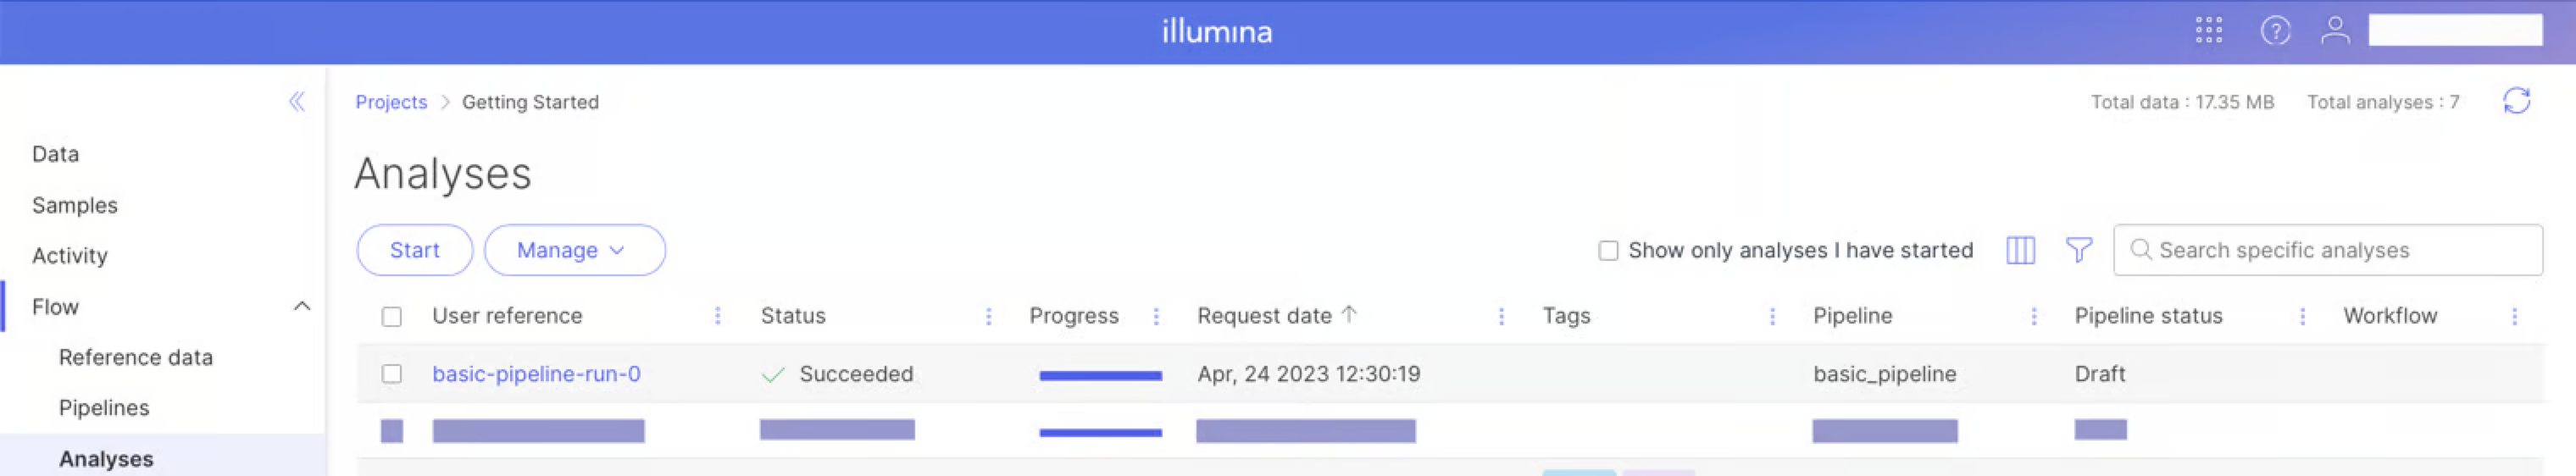
After launching the pipeline, navigate to **Projects > your\_project > Flow > Analyses**.

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-4dac9b9d26cf48f25b171b275ab53544ab1d7210%2Fimage%20(148).png?alt=media" alt=""><figcaption></figcaption></figure>

The analysis status will be visible from the Analyses view. The Status will transition through the analysis states as the pipeline progresses. It may take some time (depending on resource availability) for the environment to initialize and the analysis to move to the *In Progress* status. Once the pipeline succeeds, the analysis record will show *Succeeded* as status.

{% hint style="info" %}
This may take considerable time if it is your first analysis due to the required resource management.
{% endhint %}
{% endstep %}

{% step %}

### Details

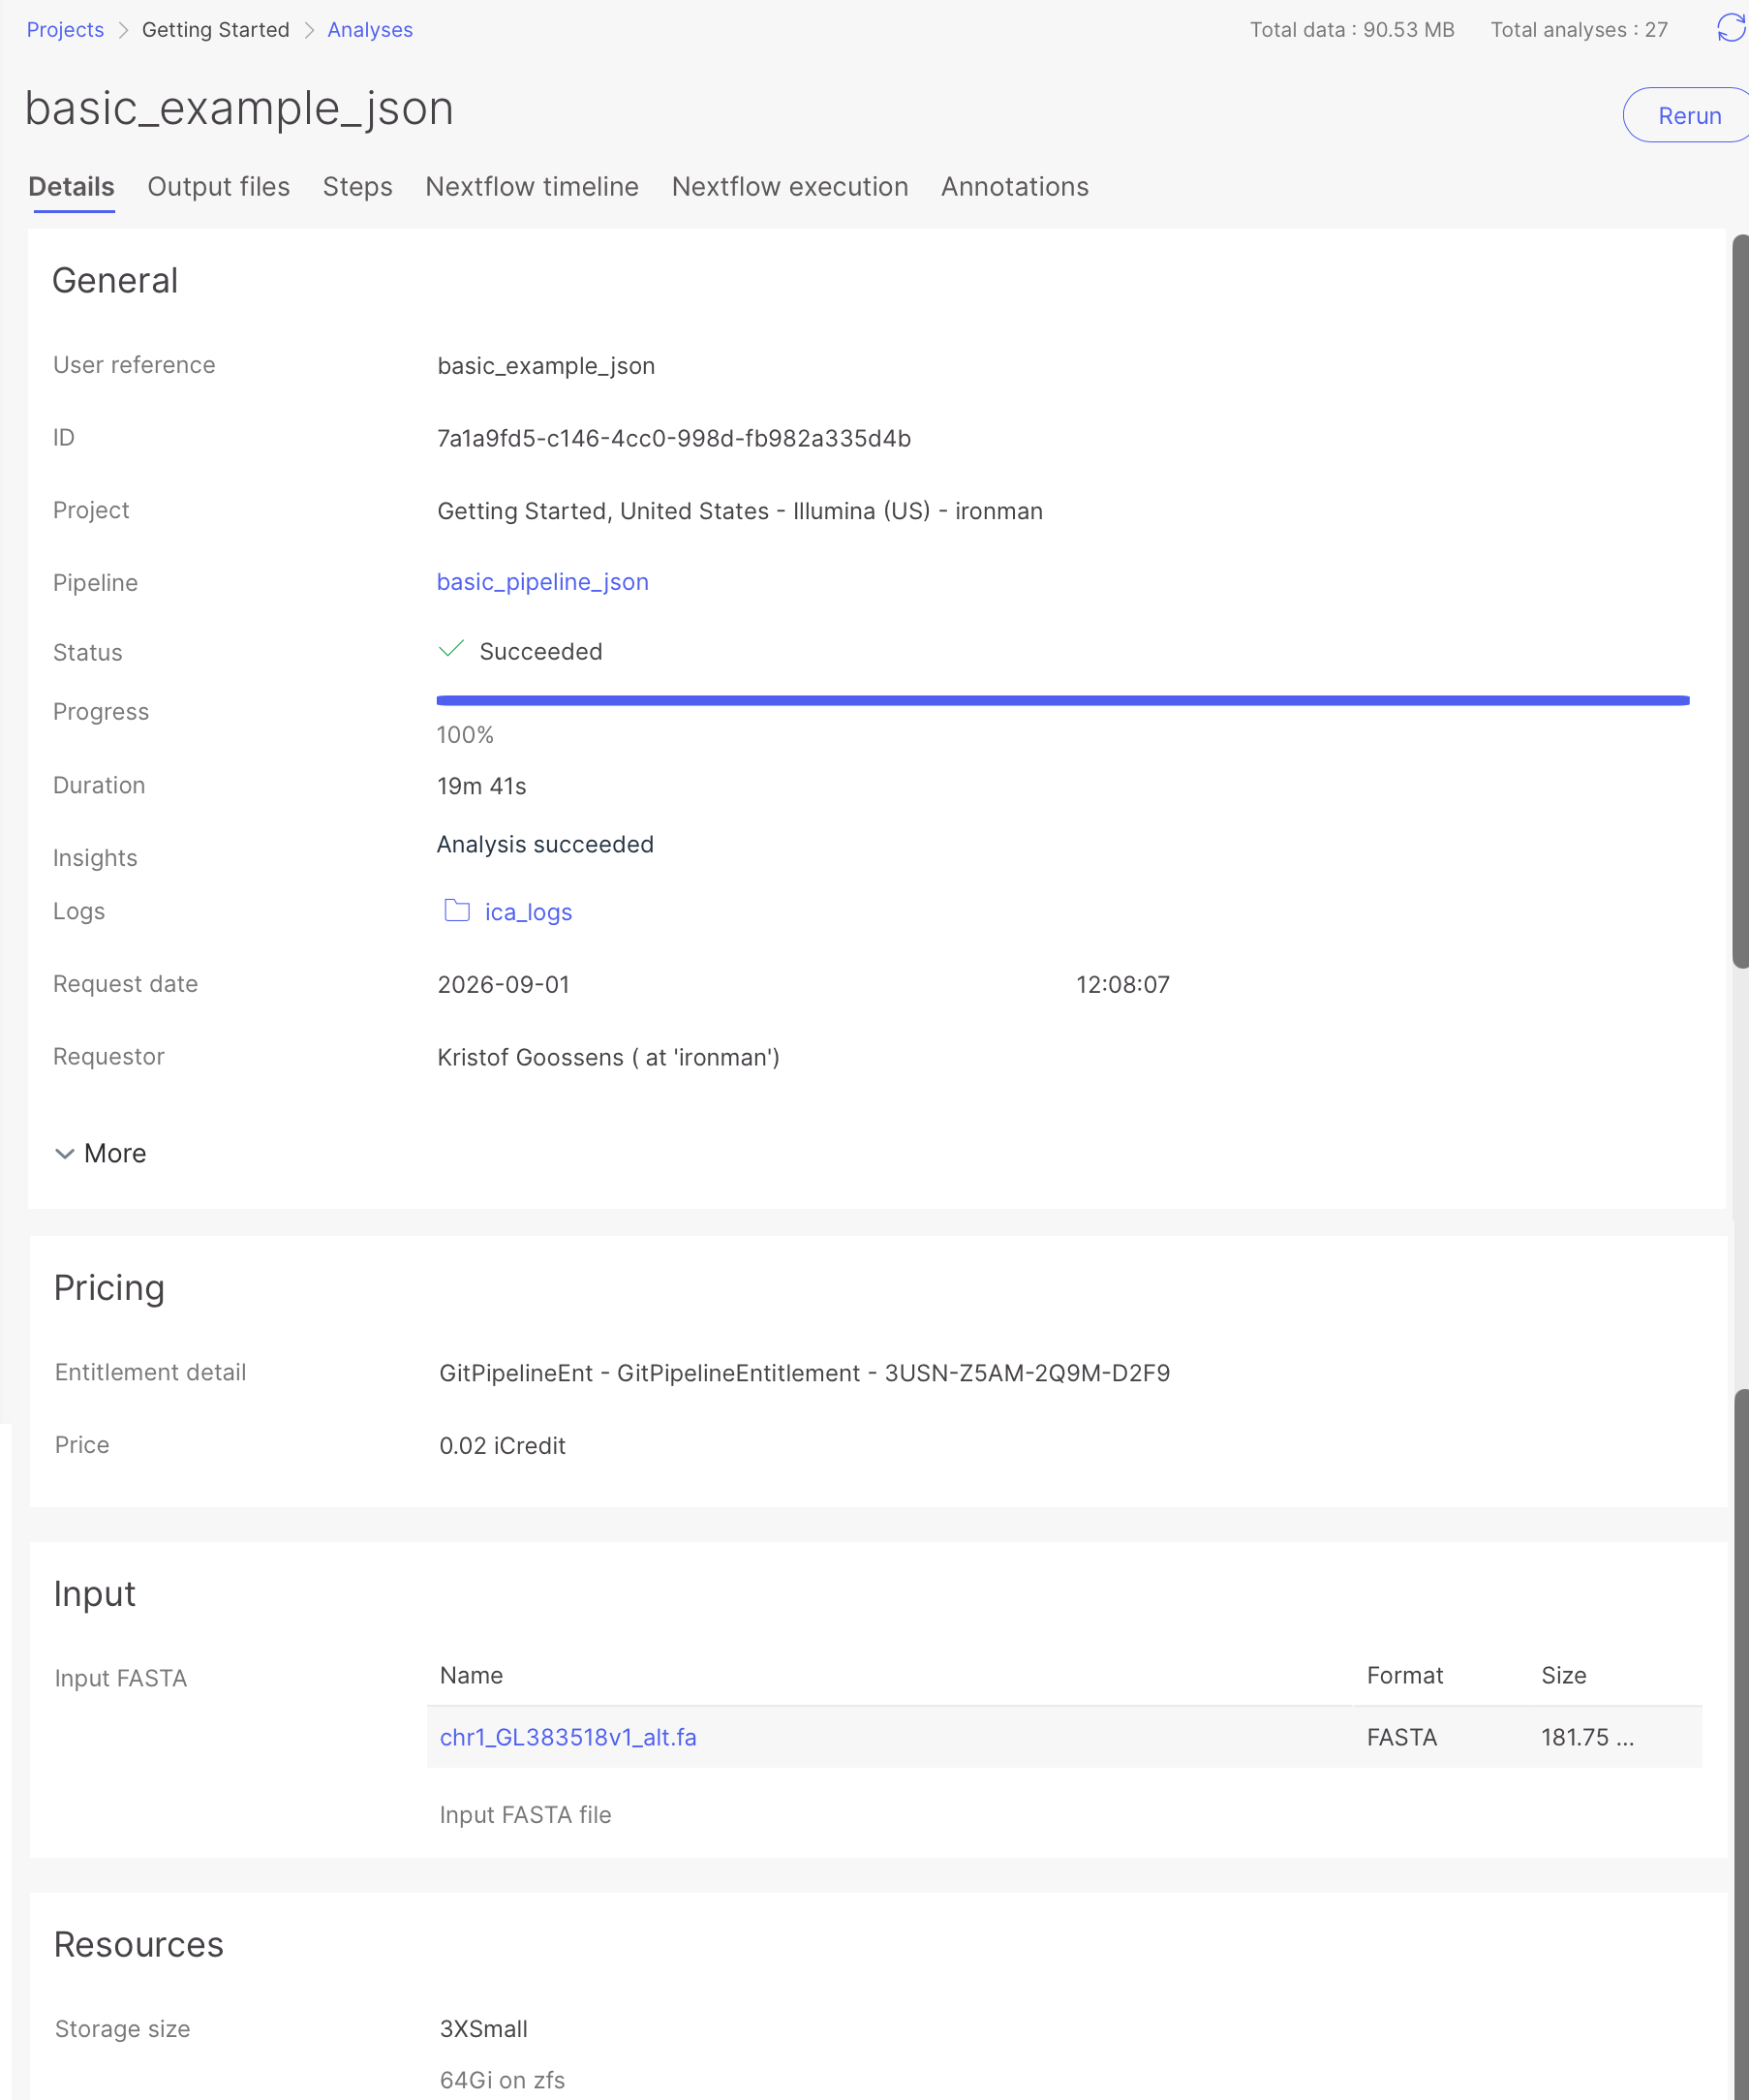
Once the analysis has succeeded, open the analysis details for more information.

<div align="left"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-78f32914a1cfe295877100c7939e1bc40b8af5e8%2Fimage%20(165).png?alt=media" alt="" width="563"><figcaption></figcaption></figure></div>
{% endstep %}

{% step %}

### Logs

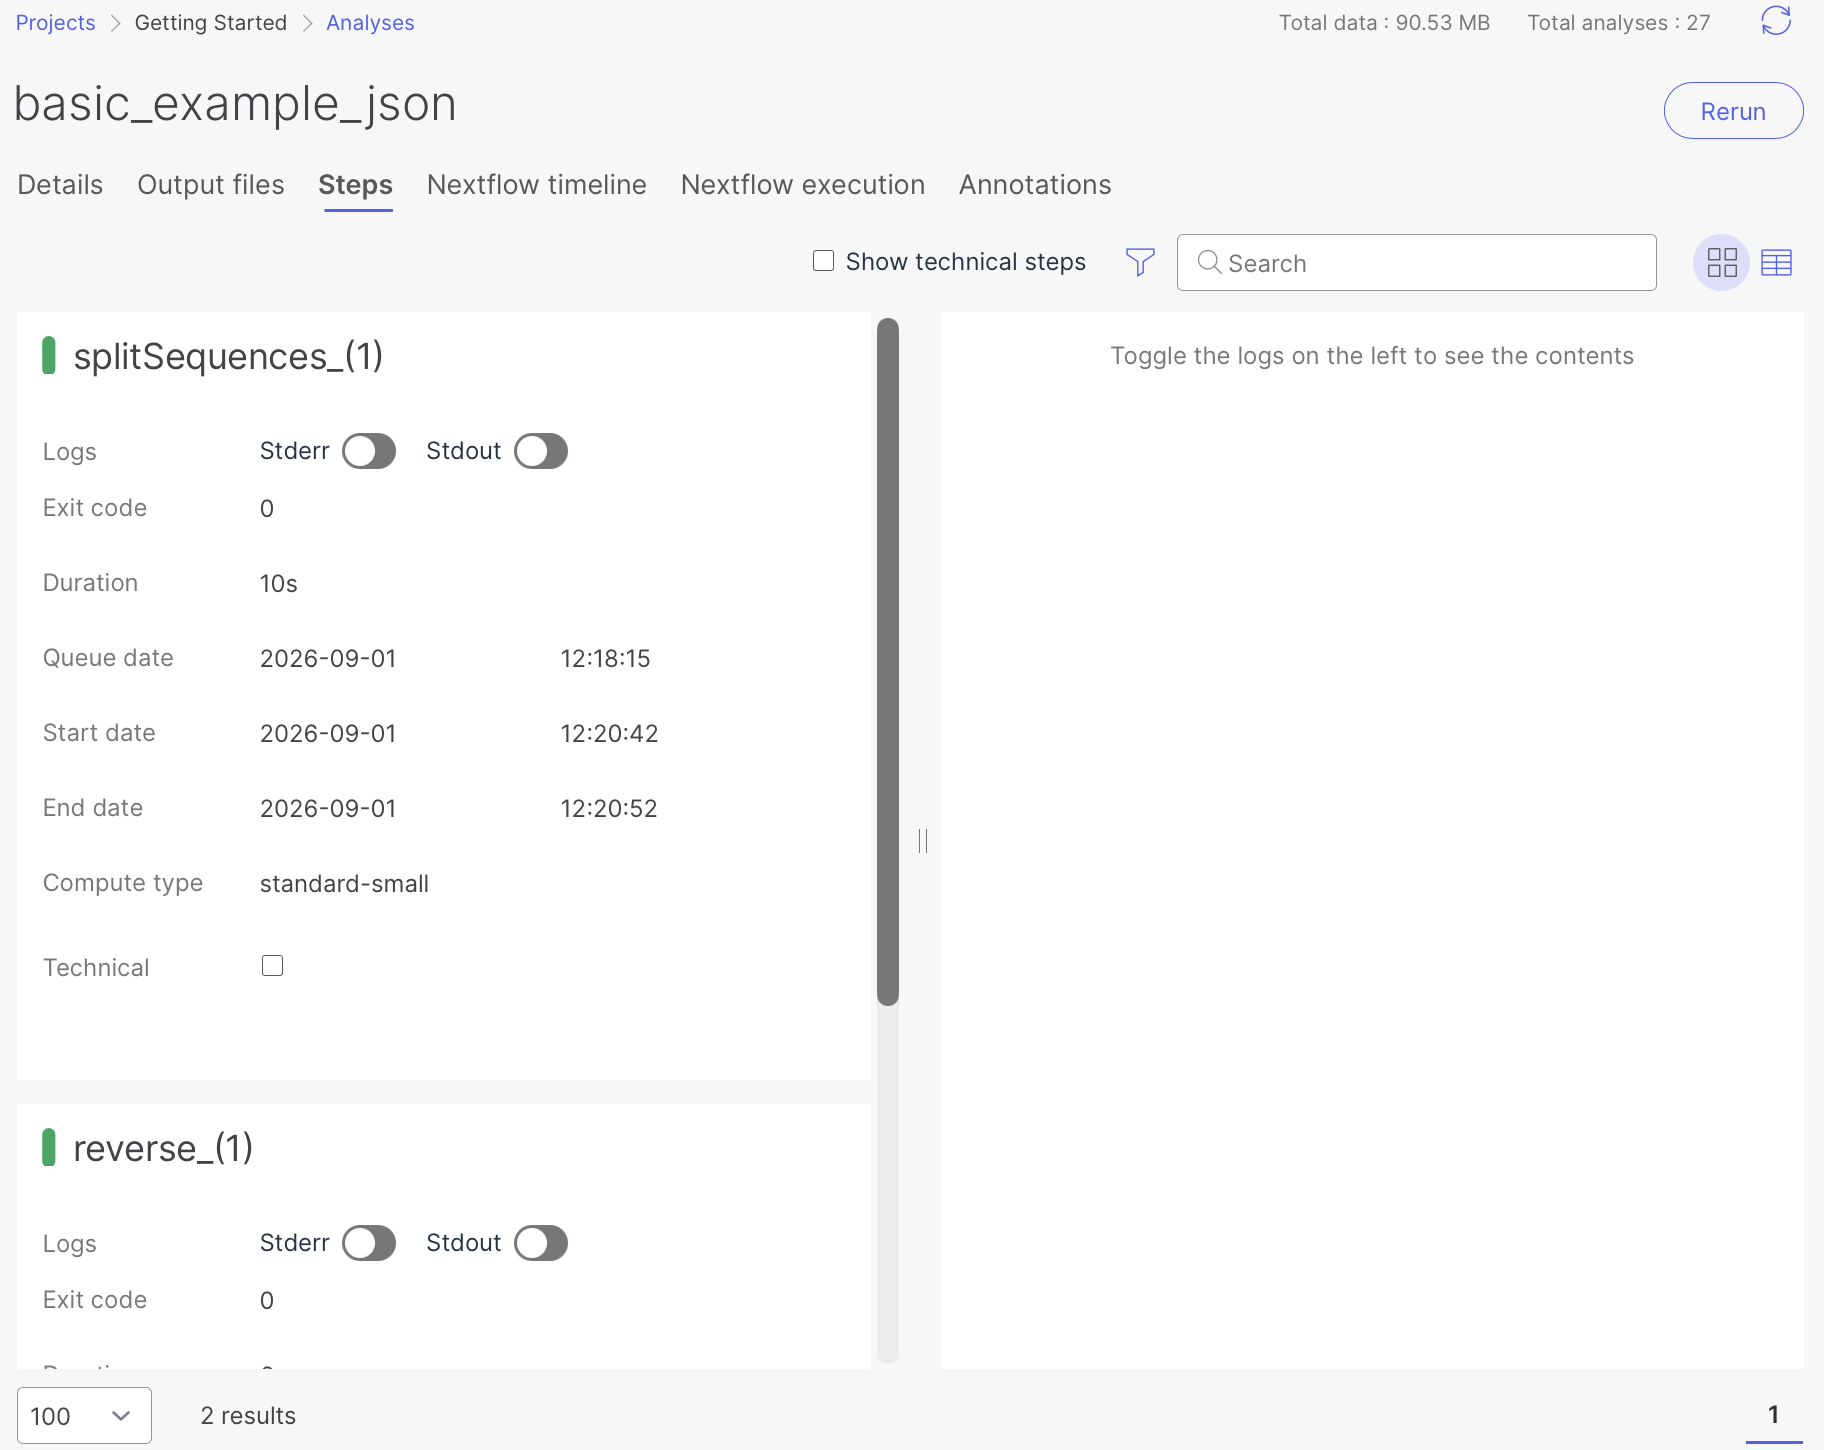
From the analysis view, the logs produced by each process within the pipeline are accessible via the **Steps** tab.

<div align="left"><figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-beb4cff0be691b5601ee58ee44349c86ab366d33%2Fimage%20(166).png?alt=media" alt="" width="563"><figcaption></figcaption></figure></div>
{% endstep %}
{% endstepper %}

## Viewing the Results

Analysis outputs are written to an output folder in the project with the naming convention `{Analysis User Reference}-{Pipeline Code}-{GUID}`. (1)

In the analysis output folder you will find the files generated by the analysis processes written to the `out` folder. In this tutorial, the file `test.txt` (2) is written to by the `reverse` process. Navigating to the analysis output folder, opening the `test.txt` file details, and selecting the VIEW tab (3) shows the output file contents.

Use the **download** button (4) if you want to download the data to the local machine.

<figure><img src="https://3193631692-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2F-MWUqIqZhOK_i4HqCUpT%2Fuploads%2Fgit-blob-16d4d387d23350262389b389a62c0e86c1cbcbc1%2Fimage%20(145).png?alt=media" alt=""><figcaption></figcaption></figure>


---

# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.

## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.

Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:

```
GET https://help.connected.illumina.com/connected-analytics/tutorials/nextflow.md?ask=<question>&goal=<user_goal>
```

`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.

The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.

Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.