> For the complete documentation index, see [llms.txt](https://help.connected.illumina.com/llms.txt). Markdown versions of documentation pages are available by appending `.md` to page URLs; this page is available as [Markdown](https://help.connected.illumina.com/connected-analytics/tutorials/nextflow/scatter-gather-nextflow.md).
# Nextflow: Scatter-gather Method
Nextflow supports scatter-gather patterns natively through Channels. The initial [example](/connected-analytics/tutorials/nextflow.md) uses this pattern by splitting the FASTA file into chunks to channel *records* in the task **splitSequences**, then by processing these chunks in the task **reverse**.
In this tutorial, we will create a pipeline which will split a TSV file into chunks, sort them, and merge them together.
## Creating the pipeline
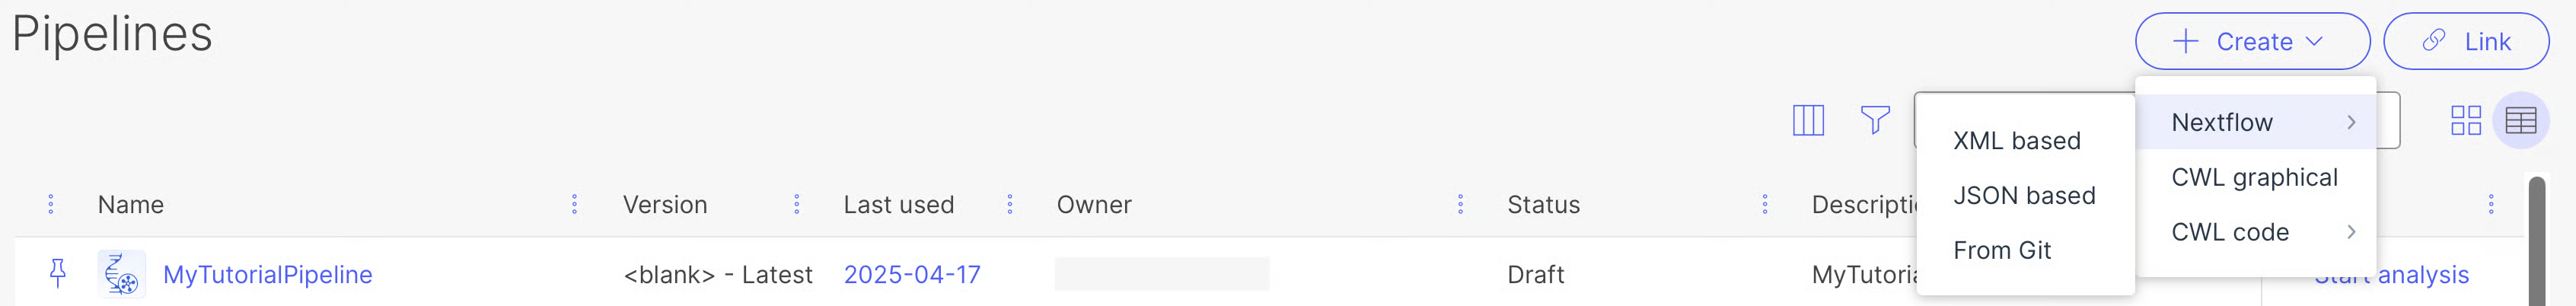
Select **Projects > your\_project > Flow > Pipelines**. From the **Pipelines** view, click the **+Create > Nextflow** **> XML based** button to start creating a Nextflow pipeline.
In the **Details** tab, add values for the required *Code* (unique pipeline name) and *Description* fields. *Nextflow Version* and *Storage size* defaults to preassigned values.
First, we present the individual processes. Select **+Nextflow files > + Create** and label the file **split.nf**. Copy and paste the following definition.
```groovy
process split {
container 'public.ecr.aws/lts/ubuntu:25.10'
pod annotation: 'scheduler.illumina.com/presetSize', value: 'standard-small'
cpus 1
memory '512 MB'
input:
path x
output:
path("split.*.tsv")
"""
split -a10 -d -l3 --numeric-suffixes=1 --additional-suffix .tsv ${x} split.
"""
}
```
Next, select **+Create** and name the file **sort.nf**. Copy and paste the following definition.
```groovy
process sort {
container 'public.ecr.aws/lts/ubuntu:25.10'
pod annotation: 'scheduler.illumina.com/presetSize', value: 'standard-small'
cpus 1
memory '512 MB'
input:
path x
output:
path '*.sorted.tsv'
"""
sort -gk1,1 $x > ${x.baseName}.sorted.tsv
"""
}
```
Select **+Create** again and label the file **merge.nf**. Copy and paste the following definition.
```groovy
process merge {
container 'public.ecr.aws/lts/ubuntu:25.10'
pod annotation: 'scheduler.illumina.com/presetSize', value: 'standard-small'
cpus 1
memory '512 MB'
publishDir 'out', mode: 'symlink'
input:
path x
output:
path 'merged.tsv'
"""
cat $x > merged.tsv
"""
}
```
Add the corresponding main.nf file by navigating to the **Nextflow files > main.nf** tab and copying and pasting the following definition.
```groovy
nextflow.enable.dsl=2
include { sort } from './sort.nf'
include { split } from './split.nf'
include { merge } from './merge.nf'
params.myinput = "test.test"
workflow {
input_ch = Channel.fromPath(params.myinput)
split(input_ch)
sort(split.out.flatten())
merge(sort.out.collect())
}
```
Here, the operators *flatten* and *collect* are used to transform the emitting channels. The *Flatten* operator transforms a channel in such a way that every item of type Collection or Array is flattened so that each single entry is emitted separately by the resulting channel. The collect operator collects all the items emitted by a channel to a List and return the resulting object as a sole emission.
Finally, copy and paste the following XML configuration into the **XML Configuration** tab.
```xml
myinput
```
Click the Generate button (at the bottom of the text editor) to preview the launch form fields.
Click the **Save** button to save the changes.
## Running the pipeline
Go to the **Pipelines** page from the left navigation pane. Select the pipeline you just created and click **Start New Analysis**.
Fill in the required fields indicated by red "\*" sign and click on **Start** button. You can monitor the run from the **Analyses** page. Once the Status changes to Succeeded, you can click on the run to access the results page.
In **Projects > your\_project > Flow > Analyses > your\_analysis >** **Steps** you can see that the input file is split into multiple chunks, then these chunks are sorted and merged.
---
# Agent Instructions
This documentation is published with GitBook. GitBook is the documentation platform designed so that both humans and AI agents can read, navigate, and reason over technical content effectively. Learn more at gitbook.com.
## Querying This Documentation
If you need additional information that is not directly available in this page, you can query the documentation by asking a question.
Perform an HTTP GET request on the following URL with the `ask` and `goal` query parameters:
```
GET https://help.connected.illumina.com/connected-analytics/tutorials/nextflow/scatter-gather-nextflow.md?ask=&goal=
```
`ask` is the immediate question: it should be specific, self-contained, and written in natural language.
`goal` is what the user is ultimately trying to achieve, the reason they need the answer. Sharing it helps GitBook give you a better, more relevant answer. A goal is most helpful when it describes the outcome the user wants rather than restating the question. For example, with `ask=how do I create an API token`, a goal like `automate deployments from our CI pipeline` lets GitBook tailor the answer to that use case.
The response will contain a direct answer to the question and relevant excerpts and sources from the documentation.
Use this mechanism when the answer is not explicitly present in the current page, you need clarification or additional context, or you want to retrieve related documentation sections.